YAPZEK® ASR
Streaming speech recognition that survives real rooms.
Multilingual, noise-robust speech-to-text with voice activity detection, optional speaker diarization and sub-400 ms latency on auto-scaling GPU — or CPU-class streaming for edge devices.
YAPZEK® ASR is built for the environments where cloud recognizers fail: lecture halls, phone lines, factory floors and meeting rooms. A streaming Conformer-CTC architecture emits partial transcripts as the speaker talks, so translation and synthesis can start before the sentence ends.
The engine feeds every YAPZEK® product — Stream, talk.yapzek.ai, Phone, MantisClaw meeting recorder — and is available standalone with a WebSocket and gRPC API.
- 100% YAPZEK®-owned, no extra licence fees
- <400 ms latency with autoscale
- GPU-optimized, CPU streaming variant
- WebSocket and gRPC APIs
- Telephony 8 kHz and wideband input
Streaming partials
Words appear as they are spoken; downstream translation and TTS start early.
Noise-robust + VAD
Voice activity detection and noise robustness tuned on real telephony and room audio.
Diarization
Optional speaker diarization for meetings, interviews and panels.
Multilingual
Turkish-first, 20+ languages, accent tolerant.
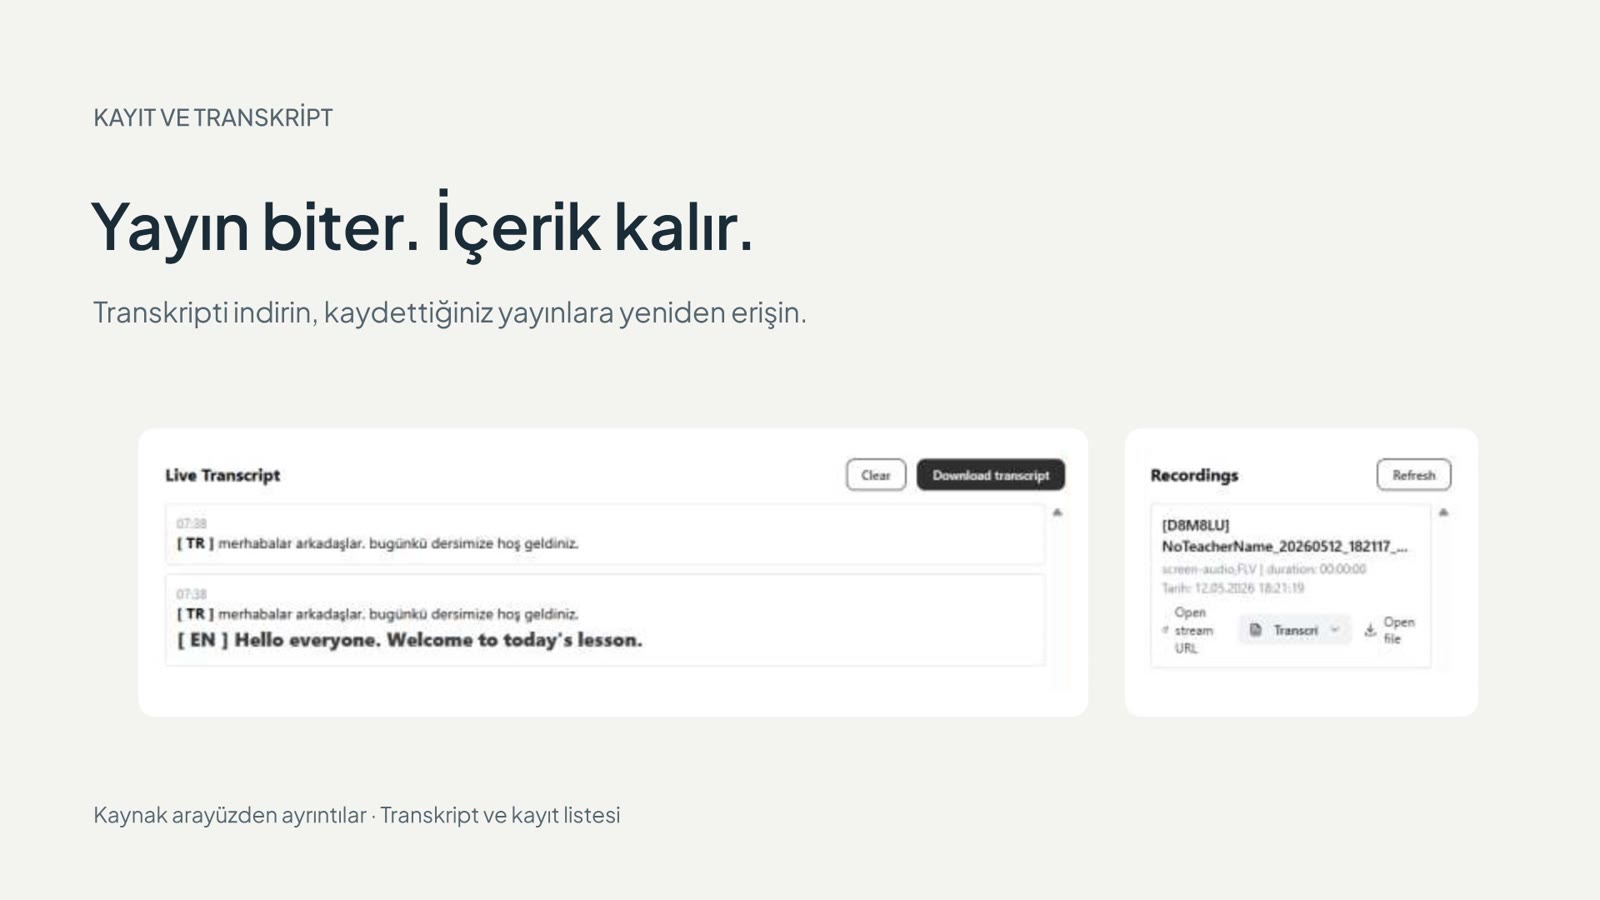
Live transcript with source and target languages
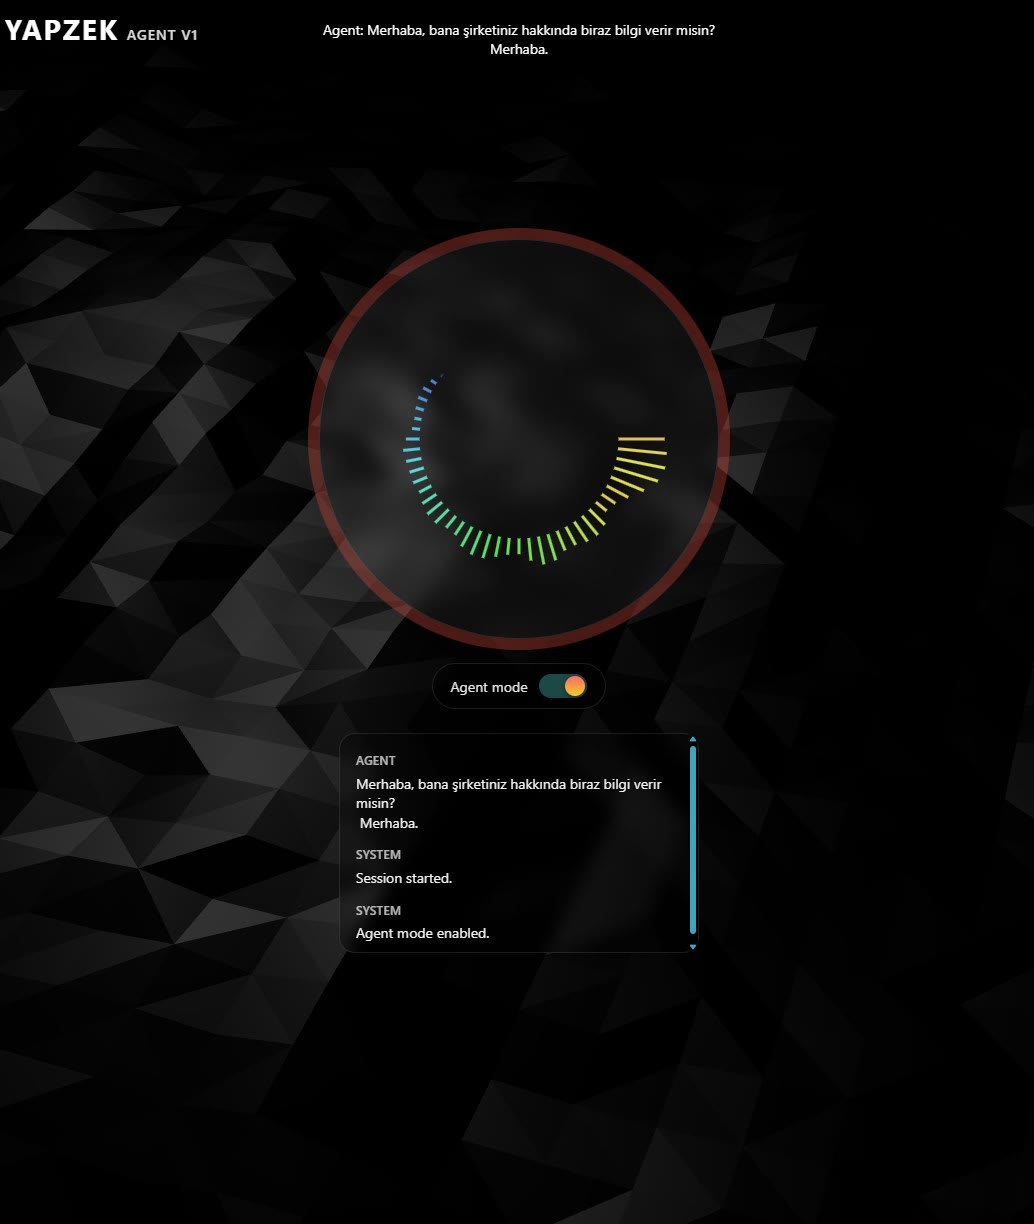
Agent v1 live recognition console
- Architecture
- Streaming Conformer-CTC
- Latency
- <400 ms, partials ~150 ms
- Input
- 8 kHz telephony → 48 kHz
- API
- WebSocket, gRPC
Ready to put AI on your own infrastructure?
Tell us about your environment, your data boundary and your latency target. We will design the pipeline with you and bring it live within days, not months.