YAPZEK® TTS
Expressive neural speech. Telephony to studio quality.
A 100% YAPZEK®-owned text-to-speech engine: natural, emotional voices, multi-accent support, real-time voice cloning and sub-400 ms response — optimized for 8 kHz μ-law telephony and 16–44 kHz output.
YAPZEK® TTS started as Türkiye's first fully domestic Turkish neural voice engine and now serves 20+ languages. The model family includes a 120-million-parameter streaming architecture that runs on CPU-class hardware for edge deployments and scales on GPU for thousands of concurrent streams.
Multi-speaker dialogue, emotion control, speech-rate control and real-time cloning let one engine produce call-center prompts, podcasts, avatar voices and broadcast audio with a consistent brand sound. No extra licence fees, ever.
- 100% YAPZEK®-owned, no extra licence fees
- <400 ms real-time response
- Multi-accent, 20+ languages
- Streaming architecture, CPU or GPU
- On-prem or SaaS
Real-time cloning
Clone a voice and synthesize in parallel with the text stream — around 200 ms latency.
Emotion & prosody
Calm, excited, angry, corporate: emotion and speech-rate are controllable per utterance.
Telephony-optimized
Native 8 kHz μ-law output for SIP / IVR, plus 16–44 kHz for web and studio.
Multi-speaker dialogue
Script multi-voice conversations and podcasts from numbered text lines.
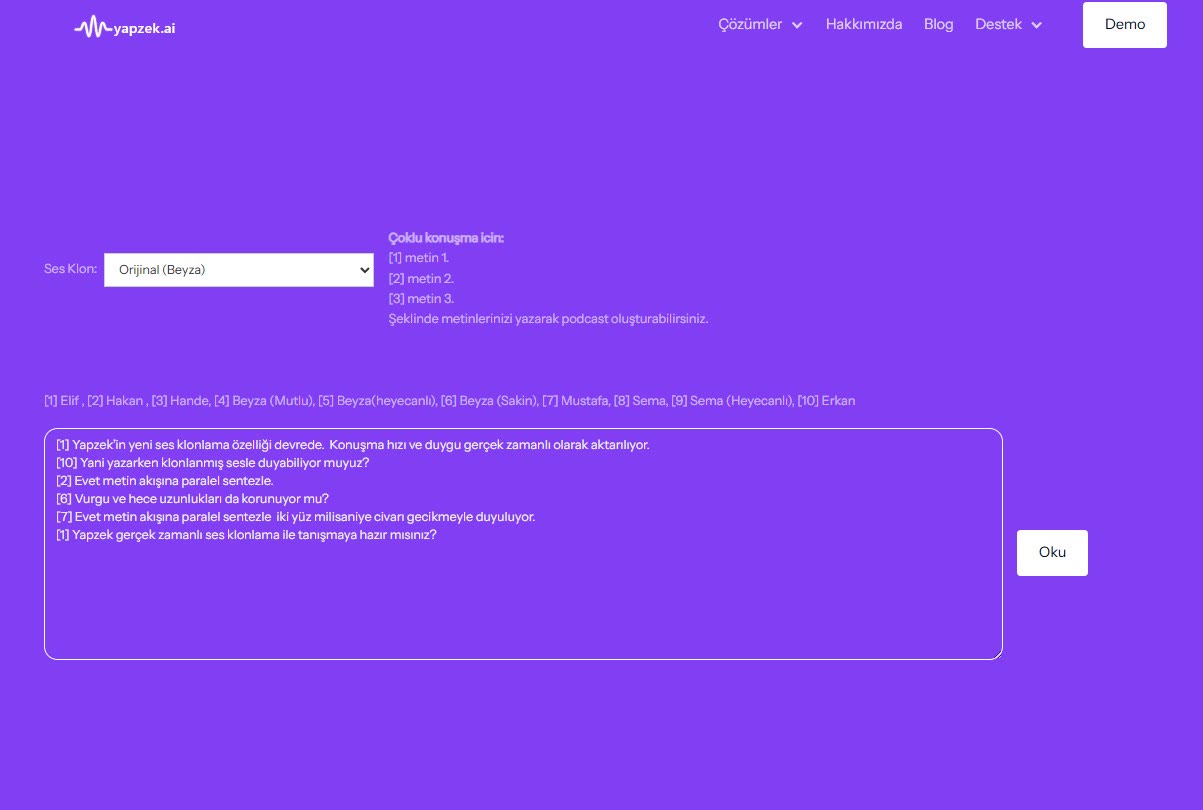
Multi-speaker voice cloning studio
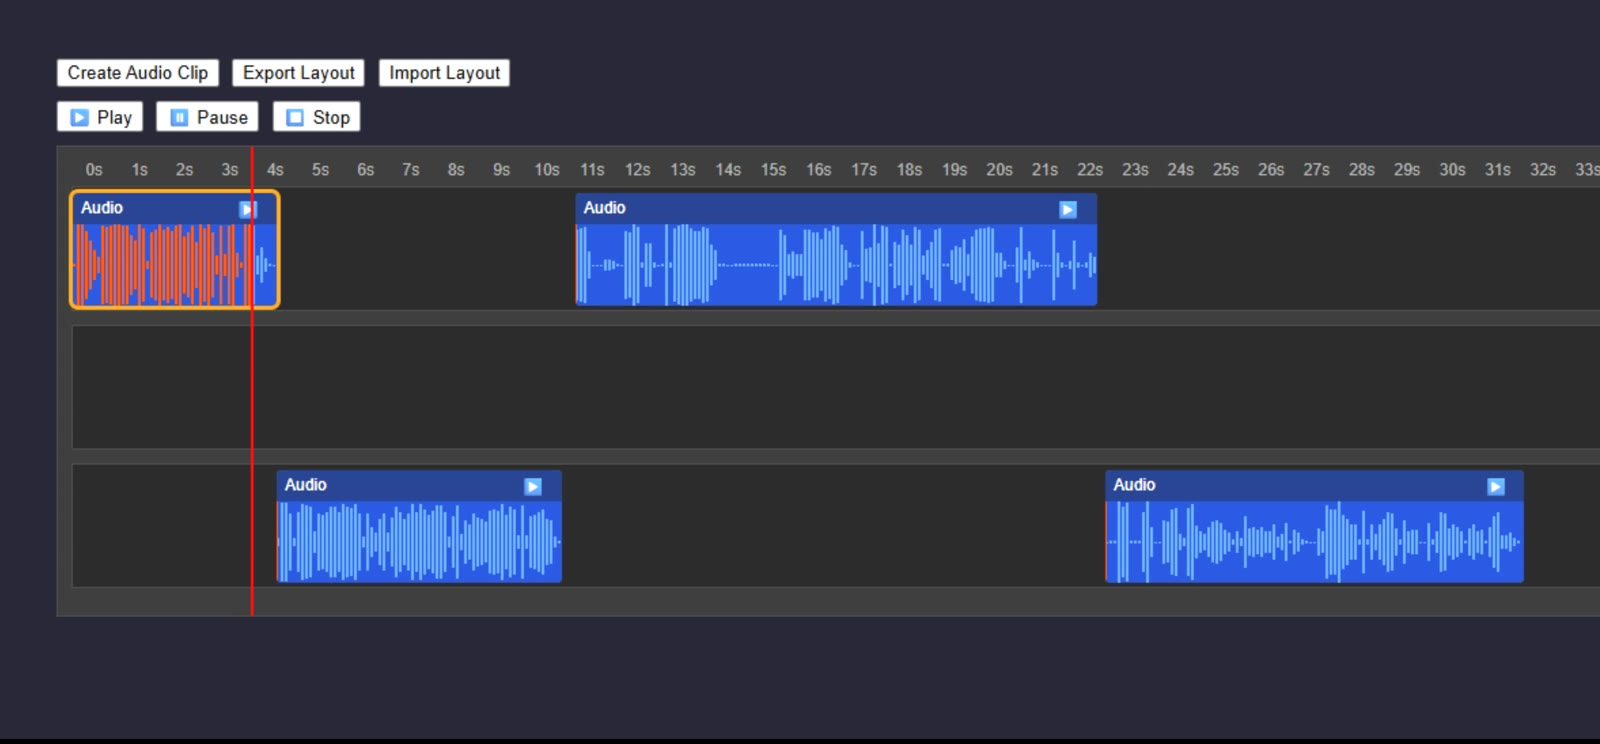
Audio timeline editor
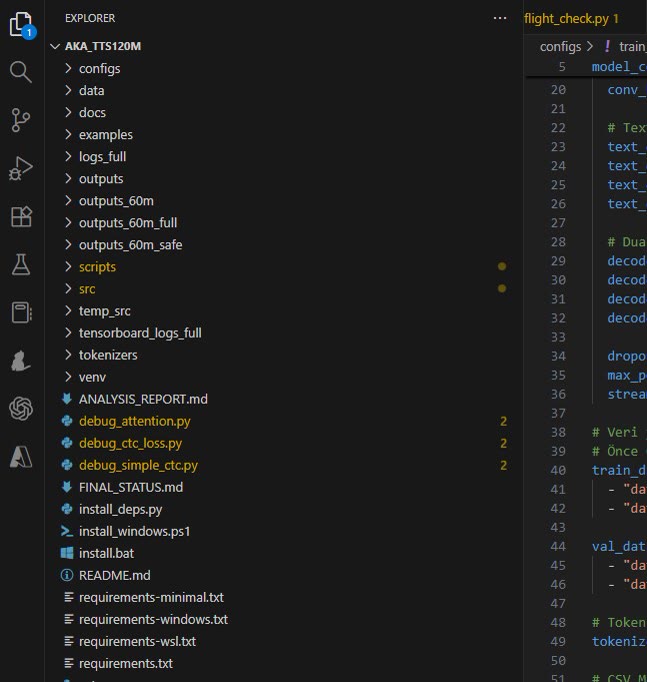
120M-parameter model training workspace
- Latency
- <400 ms first audio, ~200 ms streaming
- Output
- 8 kHz μ-law, 16 / 22 / 44 kHz PCM
- Model
- 120M-parameter streaming family
- Hardware
- CPU for edge, GPU for scale
Ready to put AI on your own infrastructure?
Tell us about your environment, your data boundary and your latency target. We will design the pipeline with you and bring it live within days, not months.